Worked · October 28, 2026
Can a mistake become a test?
Two preserved failures became local reference tests. The old answer fails, the current agent passes, and the same mistake is blocked in those cases.
Stephen Luc · Lifecycle marketing and automation
I’ve been building and teaching since 2003. My work brings email, courses, content and customer journeys together. I use AI agents to research and build, then check what they produce.
What I do
01
Who researches, who builds, who checks, and in what order. Agents from different AI companies, each on work it can handle.
02
What to hand an agent, when to hand it over, and how to check that the next session has what it needs.
03
Builders test and review their work first. Separate reviewers and evals add another check, with records of what actually ran.
Proof
On September 26, 2026, my crew reviewed Misfit Hollow, an app we built. No agent certified its own work. Every number below comes from the run’s own records.
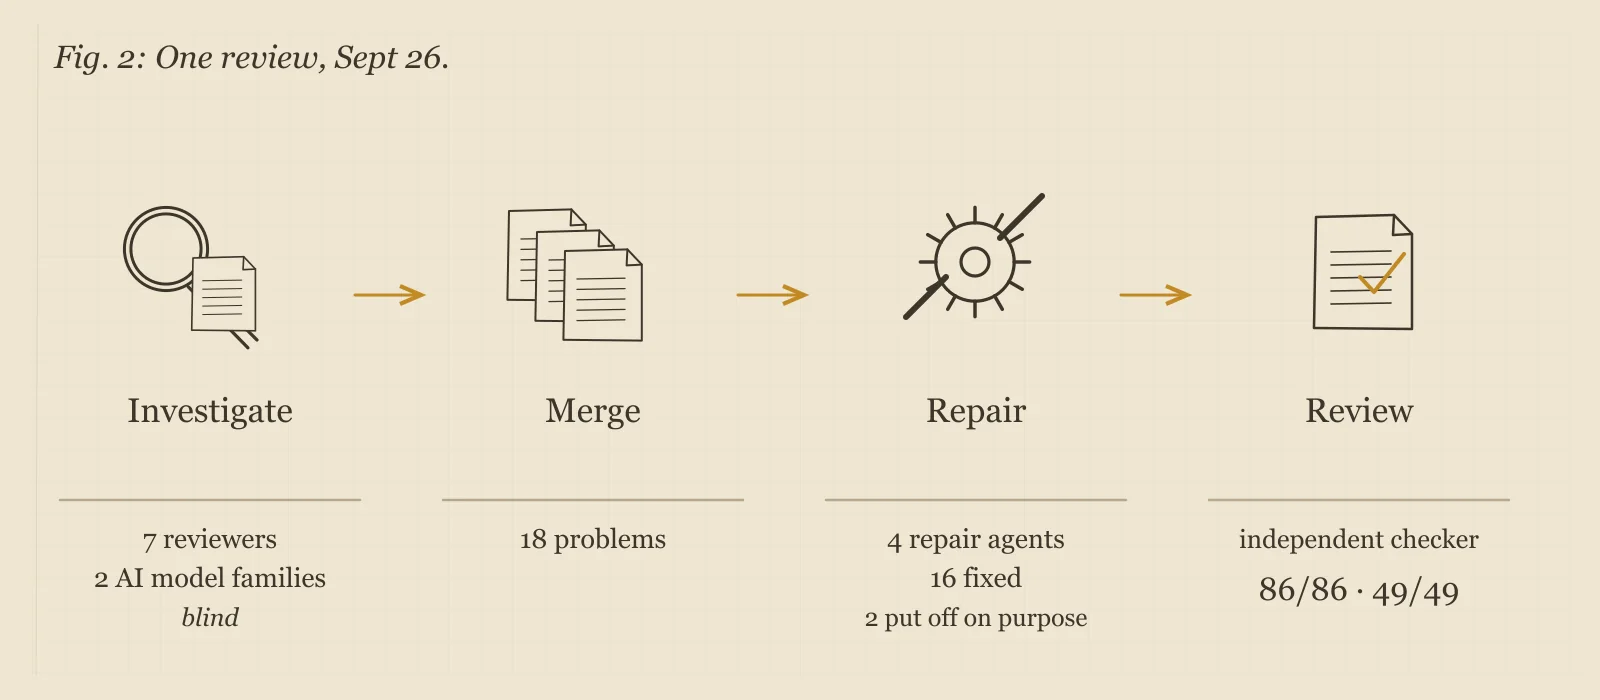
1 · Investigate
7 reviewers from 2 AI model families look separately, blind to each other.
2 · Merge
Their reports merge into 18 problems and missing tests.
3 · Repair
4 repair agents fix 16. Two are put off on purpose, named, not hidden.
4 · Review
An independent checker confirms: 86/86 code checks, 49/49 browser checks.
What it doesn’t prove: that every run goes this well. The November 10, 2026 recount found 143 substantive workflow attempts: 105 completed, 27 failed and 11 unresolved. App work, research and discussions are counted; installation and toy checks are separate. These are attempts, not shipped apps, and the failures stay in.
See the full run →From the Lab
We keep the failed and inconclusive results alongside the successes.
Worked · October 28, 2026
Two preserved failures became local reference tests. The old answer fails, the current agent passes, and the same mistake is blocked in those cases.
Mixed result · October 8, 2026
One UI guide scored higher in 5 of 30 matched comparisons, tied in 17 and lower in 8. Two CSS tasks; no consistent upgrade in this batch.
Full count · October 27, 2026
56,474 verdicts over 3,322 records. 46,364 could not be verified from the available evidence.
What we’ve built
Most of them started with one question: why is an agent doing this by hand?
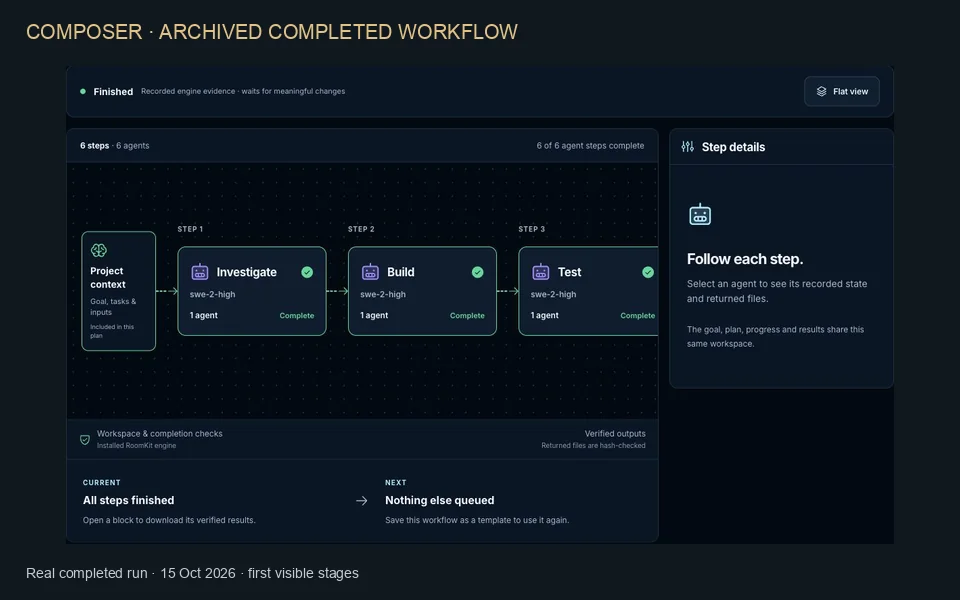
Archived completed workflow · not a live run
Give your AI team a job and follow the work from plan to result.
Private tool, running on my own machines and connected cloud workspaces. Its page shows the parallel trials, outcomes and current limits.
How Hearthside Crew works →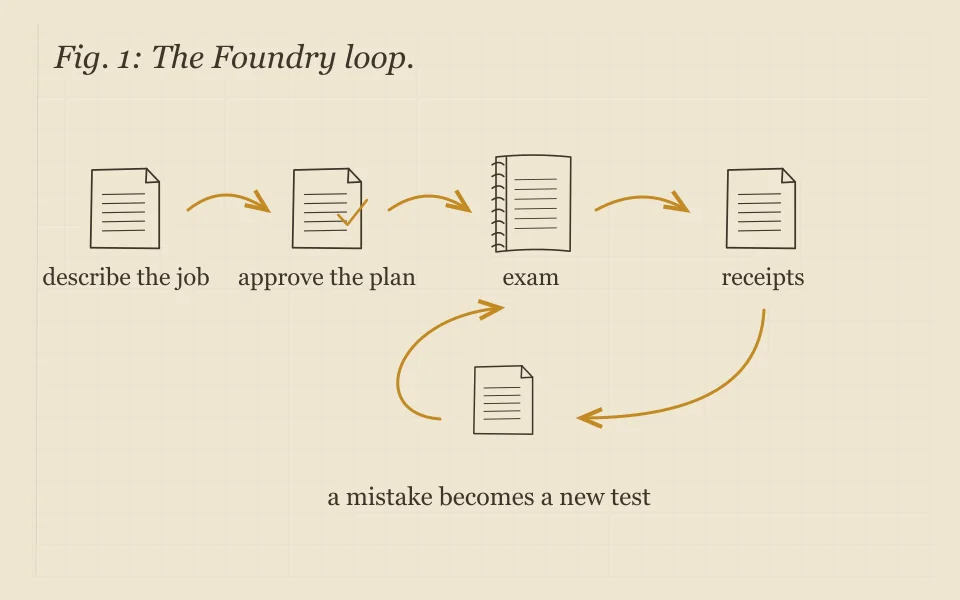
Give an agent a clear job, try it on examples, and keep track of what needs to improve.
How Foundry works →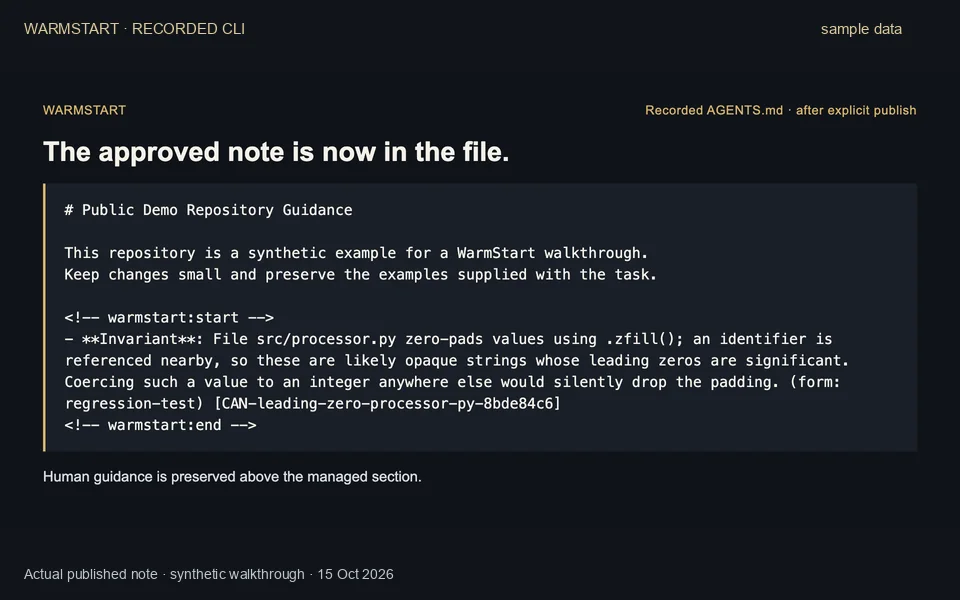
Recorded terminal handoff · synthetic sample repository
Give a new agent a short set of project notes, with links to the code behind them.
About WarmStart →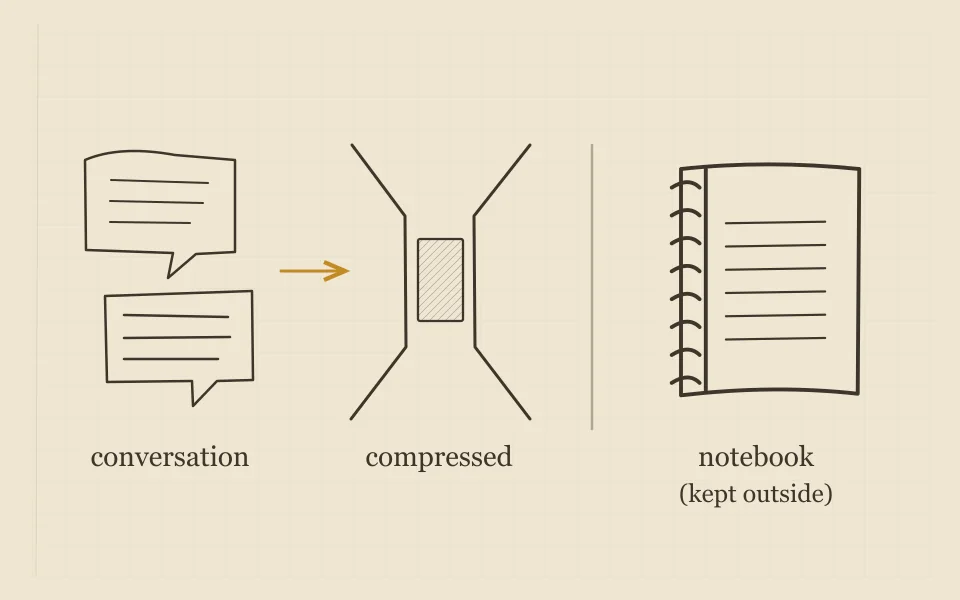
Keep a working note outside the chat so a Codex agent can find the next step after its conversation is shortened.
Available on GitHub under the MIT License. Source ↗ · The Continuity Lab
About Continuity →Where it came from
I’ve always been the person who automates the business behind the product. The crew used to be people. Now it’s agents.
Since 2003
Built a video-training business and partnered on products with Russell Brunson, Jeremy Gislason and Simon Hodgkinson. My courses have reached 26,919 learners on Udemy ↗.
Earlier marketing work
I built a list of about 9,000 internet marketers and had top-3 affiliate finishes.
Watercolor Misfit
I co-own Watercolor Misfit, whose YouTube channel has 182K subscribers. I work on the systems behind its courses and community.
Teaching
Helped faculty and students use the systems we built. That’s where I learned to explain hard things simply.
Now
Designing the workflows, the context and the checks, and building the tools when they don’t exist yet. My story →
Audience figures updated November 3, 2026.
Email, onboarding, content reuse, or a customer journey that needs clearer steps. I can help map the work and build what’s missing.